Claude vs ChatGPT for Business (2026): Which One Should Run Your Systems?
Every founder asks the same question at some point: should the team run on Claude or on ChatGPT? Most comparisons answer it with a spec sheet or a benchmark screenshot. That doesn't help you, because your business isn't a benchmark. It's a set of jobs you run every week: writing, research, offers, outreach, reporting, code.
This guide shows you how to decide between Claude vs ChatGPT for your business in 2026. It compares both tools side by side using only what Anthropic and OpenAI document on their own pages, gives you a five step test you can run on your own work, looks at one published company story, and ends with the two Claude prompts we use to run the test. Features change fast, so everything below is stated as of September 2026.
The short version:
- For one-off questions, Claude and ChatGPT are close enough that the choice barely matters. For repeatable business systems, the differences compound.
- ChatGPT has built-in image generation on all tiers. Claude does not generate photos or illustrations, but it builds charts, diagrams and interactive visuals.
- Both offer project workspaces, connected apps, deep research and agent-style work, and both have business plans that don't train on your company data by default.
- The right choice depends on your workload: test both on three real tasks from your week, score the outputs, then standardize on one tool.
- The model is rarely the bottleneck. A clear brief (role, context, constraints, output format) matters more than which chat window it goes into.
What is the difference between Claude and ChatGPT?
Claude and ChatGPT are both general AI assistants built on large language models. Claude is made by Anthropic, ChatGPT by OpenAI. Both write, analyze files, search the web, work inside projects and connect to business apps. The practical difference for a business is less about raw intelligence and more about the surrounding toolset: ChatGPT bundles image generation and a broad consumer ecosystem, while Claude focuses on long written work, projects as a shared business brain, and agentic tools like Claude Code.
People search this both ways ("claude vs chatgpt" and "chatgpt vs claude"), but the real question is the same: which tool will your team actually use every day, and which one produces work that needs the least fixing?
The core: Claude vs ChatGPT side by side
Everything in this table comes from the vendors' own pages: Anthropic's plans page and help center, and OpenAI's ChatGPT Business overview, Images help page and Work and Codex help page. As of September 2026.
| Job | Claude | ChatGPT |
|---|---|---|
| Image generation | Does not generate photos or illustrations; builds charts, diagrams and interactive visuals instead (Anthropic) | ChatGPT Images is available on all tiers, including editing uploaded images |
| Project workspaces | Projects with their own knowledge base and custom instructions; Free has up to 5, paid plans have full access | Projects keep related chats, files and instructions together (OpenAI) |
| Agent-style work | Hand off and schedule tasks on Pro and above | ChatGPT Work handles longer multi-step tasks and can run on a schedule or trigger |
| Coding | Claude Code included from Pro | Codex included in ChatGPT plans, depending on plan and seat |
| Research | Research on paid plans, web search on all plans | Deep Research included on Business seats |
| App connections | Connectors and Skills on all plans; Claude in Chrome and Microsoft 365 from Pro | Apps and Company Knowledge on Business seats |
| Team plan | Team plan with SSO, central billing, project sharing, standard and premium seats | ChatGPT Business with admin controls, standard and premium seats, minimum 2 seats |
| Training on company data | Team: no model training on your content by default | Business: OpenAI won't train on your workspace's data |
Read the table the right way: most rows match. Both tools can run a serious business in 2026. The rows that don't match are the ones that should drive your decision. If your team produces a lot of visual content and wants it in the same tool, that tips toward ChatGPT. If your systems are long, instruction-heavy written work built on shared projects, that is where we have seen Claude earn its place.
Pricing is close as well. Both vendors publish per-seat team pricing with a standard and a premium tier in the same range. Check the Claude plans page and the ChatGPT Business overview on the day you buy, because both change often.
How to choose between Claude and ChatGPT in 5 steps
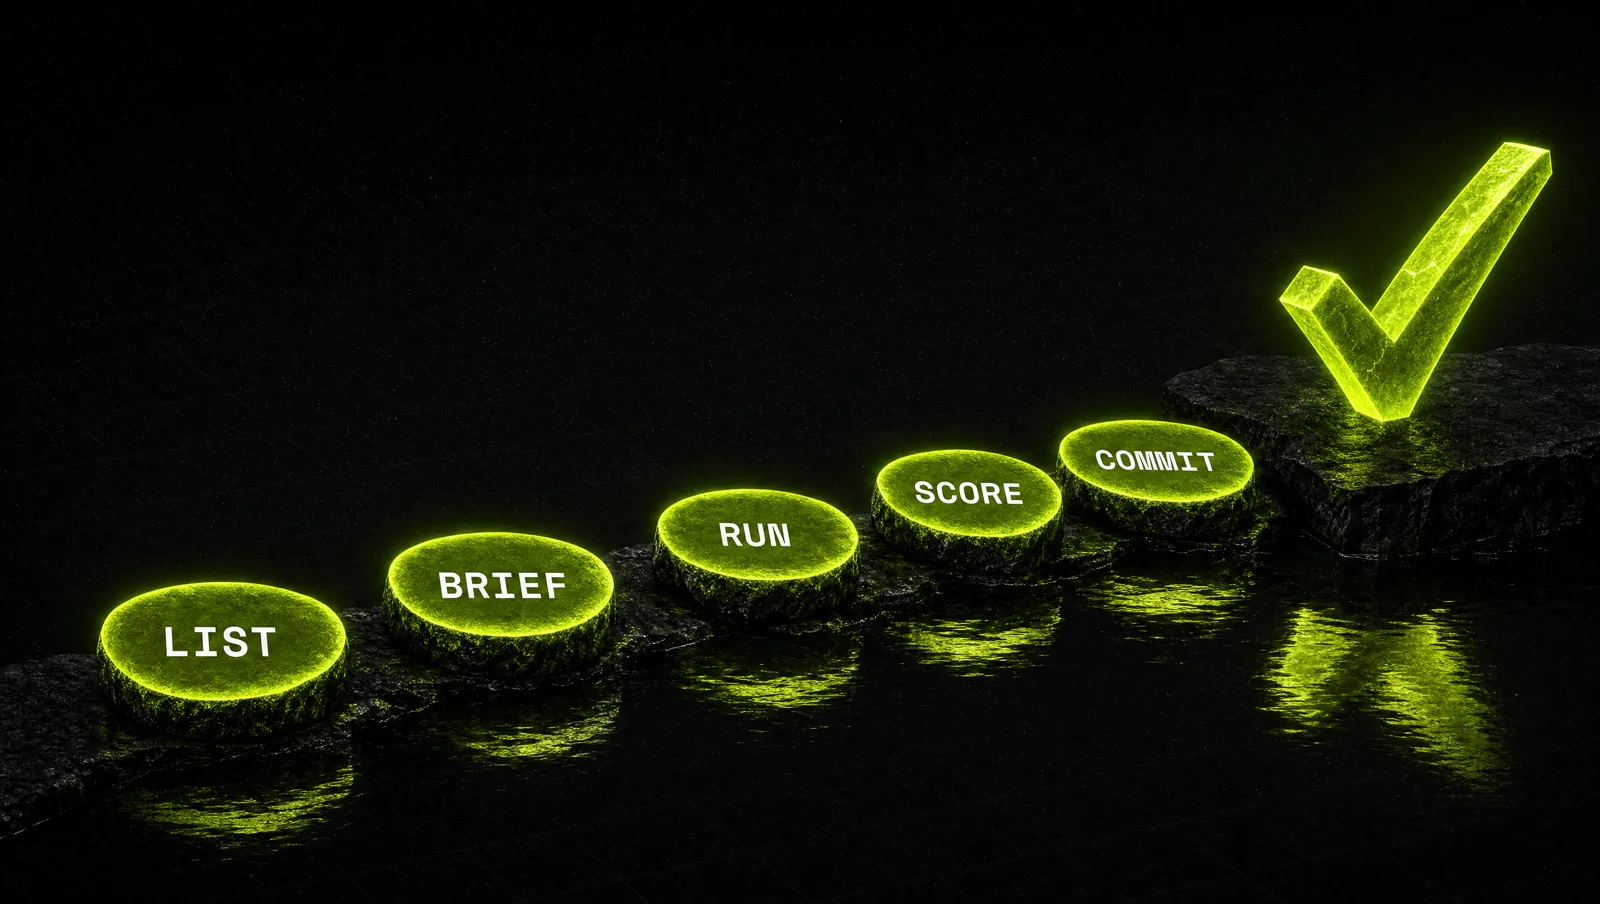
Don't pick a tool by reading reviews. Pick it by running your own work through both. This takes one afternoon.
Step 1: List the jobs you repeat every week
Write down the five to ten tasks that eat the most time: weekly newsletter, sales follow-ups, proposal drafts, customer support replies, reporting, ad creatives, code fixes. Mark each one as mostly writing, analysis, visual or code. This list is your real benchmark. Public leaderboards measure somebody else's work.
Step 2: Pick three tasks and write one brief for each
Choose the three highest-value tasks. For each, write one brief you will paste into both tools unchanged: role, context about your business, constraints, examples of good output and the exact output format. If you don't have briefs yet, our guide to Claude prompts for founders shows the structure. Same brief in both tools, or the test means nothing.
Step 3: Run both tools with the same context
Set up a project in each tool with the same files: your offer, your voice rules, a few past examples. Run each brief in both. Don't edit anything yet. Save the raw outputs side by side in one document, without labels, so you can judge them blind.
Step 4: Score the output, not the chat
For each output, score three things from 1 to 5: how closely it followed the instructions, how much editing it needs before you would ship it, and whether the facts and numbers are right. Then add the one metric that actually costs you money: minutes of editing until it's usable. Have a second person score as well if you can.
Step 5: Standardize on one tool and build the system
Add up the scores per task type. If one tool wins on writing and the other on visuals, you can run two tools, but assign each job to exactly one of them. Then stop switching. Rebuilding prompts, projects and habits in a second tool every month is a hidden tax that is bigger than most model differences. Turn the winning briefs into a project, as we describe in Claude as your operations system.
A real case: how a 25 person company picked Claude
Section is an AI upskilling company with a team of 25, according to its published customer story on claude.com. It started as a leadership training provider and moved its focus to AI upskilling in early 2023.
The way they chose a tool is the interesting part. According to the story, the CEO and COO tested Claude against other AI platforms in August 2023 by uploading their own board materials and checking how much of the board's actual feedback each tool anticipated. The story reports that Claude identified 92% of the feedback the board raised. That was their own internal test on their own documents, not a public benchmark, which is exactly why it was useful to them.
After the rollout, the story reports these results:
- 82% of team members use Claude, against a 5% benchmark for the overall workforce.
- Half the team reported at least 10% productivity gains.
- They spend about $20,000 a year on AI accounts for 25 people and estimate $150,000 to $200,000 in annual savings, roughly one to two headcount.
- The marketing team used Claude Projects to build a voice of the customer repository from survey data and market research.
Look at it through the system:
- Step 1 and 2: they didn't test with generic prompts. They used their highest-stakes real document, the board deck.
- Step 3 and 4: they compared tools on the same input and judged the output against a real answer key: what the board actually said.
- Step 5: once they picked, they built shared projects per team instead of letting everyone use whatever was open.
The lesson: Section didn't pick a tool based on hype. They ran their own work through the options, measured the result against reality and then built the system around the winner. You can run the same test on your business in an afternoon, and your result may be different from theirs. That is the point.
Three use cases
The examples below are illustrative, not real clients. They show how the same five step test lands differently depending on the business.
Use case 1: Content agency
Workload: long-form articles, newsletters and LinkedIn posts for eight clients, each with a detailed voice guide.
Test result: the deciding metric is editing minutes per draft against a 150 line voice brief. The agency builds one project per client with the voice guide, banned phrases and ten approved samples, and standardizes on whichever tool needs less rework on those briefs. Thumbnails and social images go to a separate image tool or ChatGPT Images, assigned as a separate job.
Use case 2: E-commerce brand
Workload: product descriptions, ad creatives, product images and customer support macros.
Test result: here visuals are half the workload. If the brand wants copy and images in one place, ChatGPT's built-in image generation is a real advantage. The brand might still run long support policies and supplier analysis in Claude if it scores better there, but each job gets exactly one owner.
Use case 3: SaaS founder who codes
Workload: feature work, bug fixes, onboarding emails and investor updates.
Test result: both vendors ship a coding agent, Claude Code and Codex. The founder runs the same three repository tasks through both, measures how many turns it takes to a passing test, and picks one. Written work follows whichever tool the founder already lives in all day, because switching cost matters more than small quality gaps.
How we run this with Claude
Inside CopyPasteCEO we run the comparison itself as a Claude workflow, in one chat so Claude keeps the context. Here are the two prompts, copy-paste ready. Fill in the brackets.
Prompt 1: build your test set
Make it yours · 0/2 filled
You are an operations advisor for a small business. Here is my business: [WHAT YOU SELL, TO WHOM, TEAM SIZE]. Here are the tasks I repeat every week: [LIST OF TASKS]. Pick the three tasks with the highest value if AI did them well. For each one, write a complete brief I can paste into any AI tool: role, business context, constraints, one example of good output, and the exact output format. Keep each brief under 200 words.Prompt 2: score two outputs blind
Make it yours · 0/3 filled
I ran the same brief through two AI tools. Here is the brief: [BRIEF]. Output A: [PASTE OUTPUT A]. Output B: [PASTE OUTPUT B]. Score each output from 1 to 5 on instruction following, how much editing it needs before I could publish or send it, and factual accuracy. List every concrete fix each output needs. Then tell me which one saves me more editing time and why, in three sentences.Paste the outputs without saying which tool produced them. Prompt 2 then works as a neutral judge on your own criteria. Turning the winning briefs into a project that the whole team uses is where the real payoff starts.
Where most people get stuck
Running the comparison takes an afternoon. Building the system around the winner takes a few focused rounds, and most teams stop halfway. The usual reasons:
- They test with toy prompts. "Write me a blog post" says nothing about how either tool handles your 150 line voice brief or your real client data.
- They keep switching. A new model launch every month pulls the team back into comparing instead of building projects and briefs that compound.
- They never write the brief down. Good output lives in one person's chat history instead of a shared project, so it disappears when that person is busy.
That is exactly the gap the Inner Circle is built for: ready-made playbooks to run these systems, a new playbook every week, and founders building their own AI systems next to you.